

NVIDIA GPU Cluster
Design & Deployment
NVIDIA GPU Cluster Design & Deployment
Enterprise AI Clusters — Built on NVIDIA Reference Architecture
Enterprise-Grade AI Infrastructure
Built on NVIDIA Reference Architecture
Canopy Wave designs and delivers complete GPU clusters based on NVIDIA’s official reference architecture. Our team leads the design,ensuring full alignment with NVIDIA Cloud AI Infrastructure standards from day one.
Design
Our engineering team designs the complete cluster architecture based on NVIDIA reference architectures.
Deploy
We build the cluster and deploy the underlying infrastructure software in accordance with NVIDIA Cloud AI Infrastructure standards.
Validate
Before delivery, we conduct both small-scale POC testing and full-system validation to verify functionality and performance.
Deliver
The cluster is delivered in a ready-to-use state and enters the production, monitoring, and operations phase.
Built for AI. Delivered Fast.
Expert Team
Our engineers specialize in NVIDIA GPUs, RoCE/InfiniBand networking, system architecture, and AI infrastructure. We lead end-to-end design — covering network, servers, and storage — and build clusters strictly to NVIDIA architecture standards.
Fast — Accelerated Across the Full Lifecycle
Day-0/1 Rapid Bring-Up
Data center initialization in 1–3 days. Clusters ship with GPU drivers pre-installed and networking configured — ready out of the box.
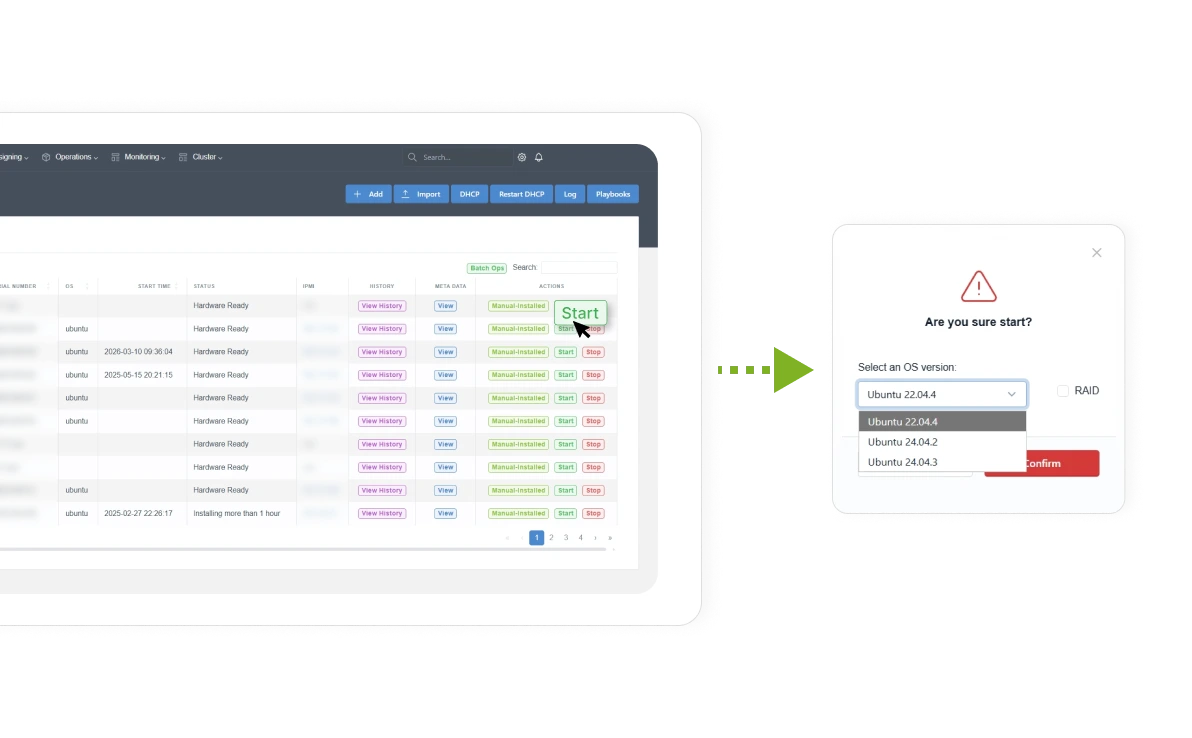
Day-2 Minute-Level Provisioning
New tenant requests trigger automatic OS reinstall, driver setup, resource isolation, and storage allocation — ready in minutes.
High-Throughput Dual-Tier Storage
Clusters integrate Weka ultra-low latency POSIX filesystem over RoCE (GPUDirect Storage ready) for model training and checkpointing, coupled with Ceph for scalable object and block datasets. Storage access is cryptographically segregated per tenant.
Enterprise-Grade Security & Reliability
Built for enterprise AI workloads with security, isolation, availability, and operational support at every layer.

SOC 2 Type II Certified
Independently audited controls covering security, availability, and confidentiality.

Zero-Trust Isolation
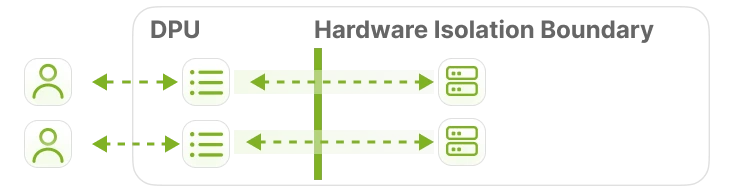
Hardware-enforced network and tenant isolation at the DPU ensures zero tenant cross-talk.

99.9% Uptime
Full-stack observability and rapid incident response help maintain reliable, continuous operations.

24/7 Expert Support
Around-the-clock technical support and an experienced operations team provide rapid response, so your team can stay focused on your business.
Global Data Center Footprint
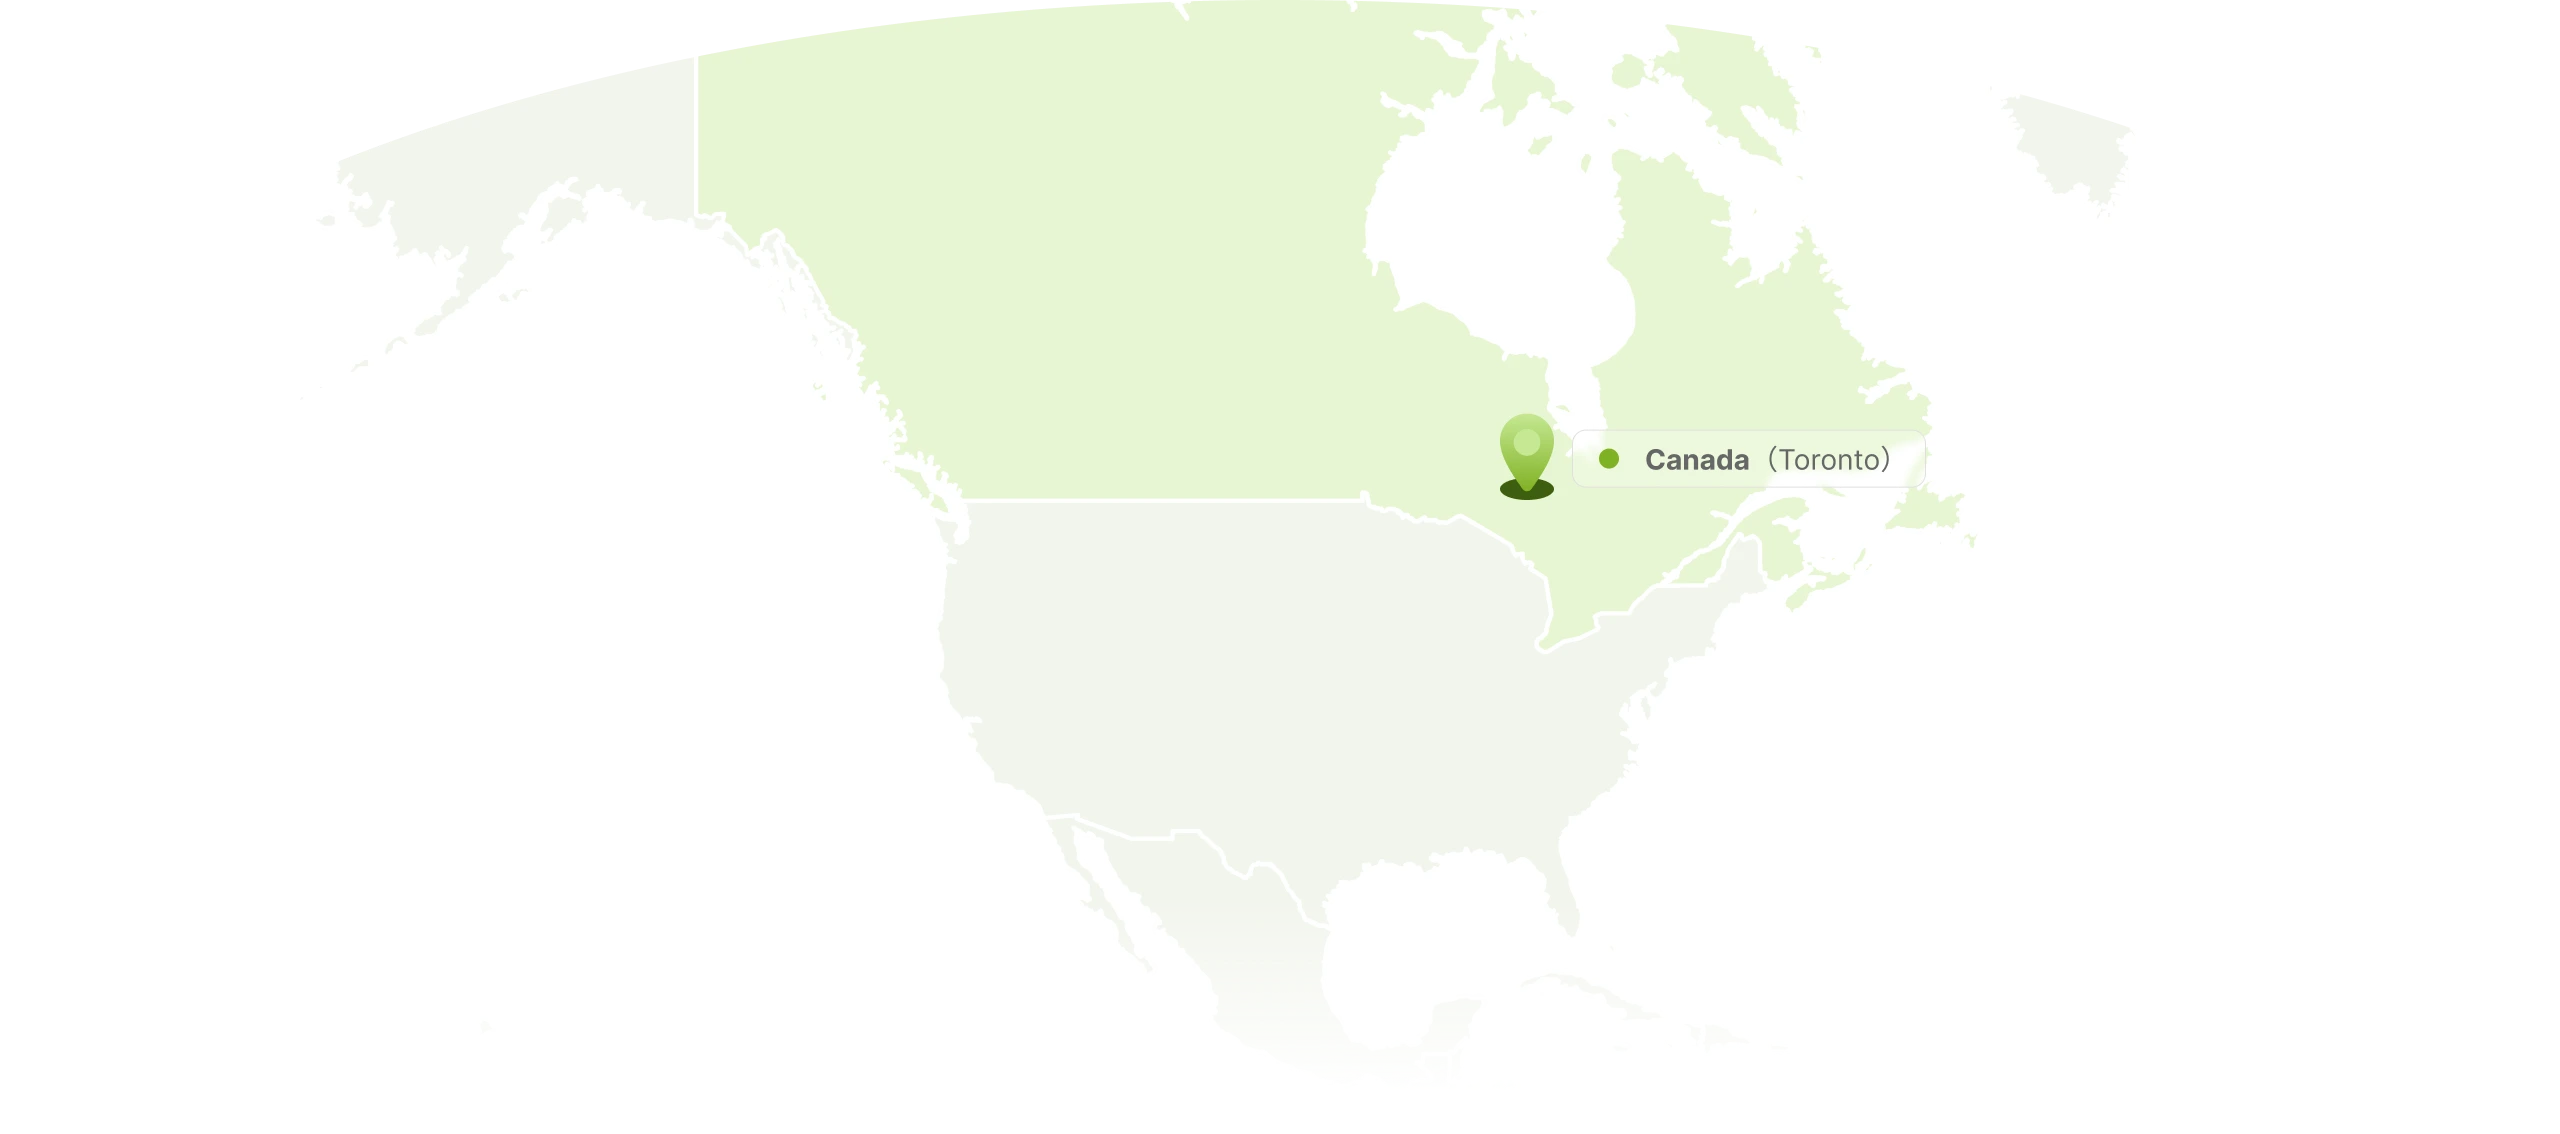
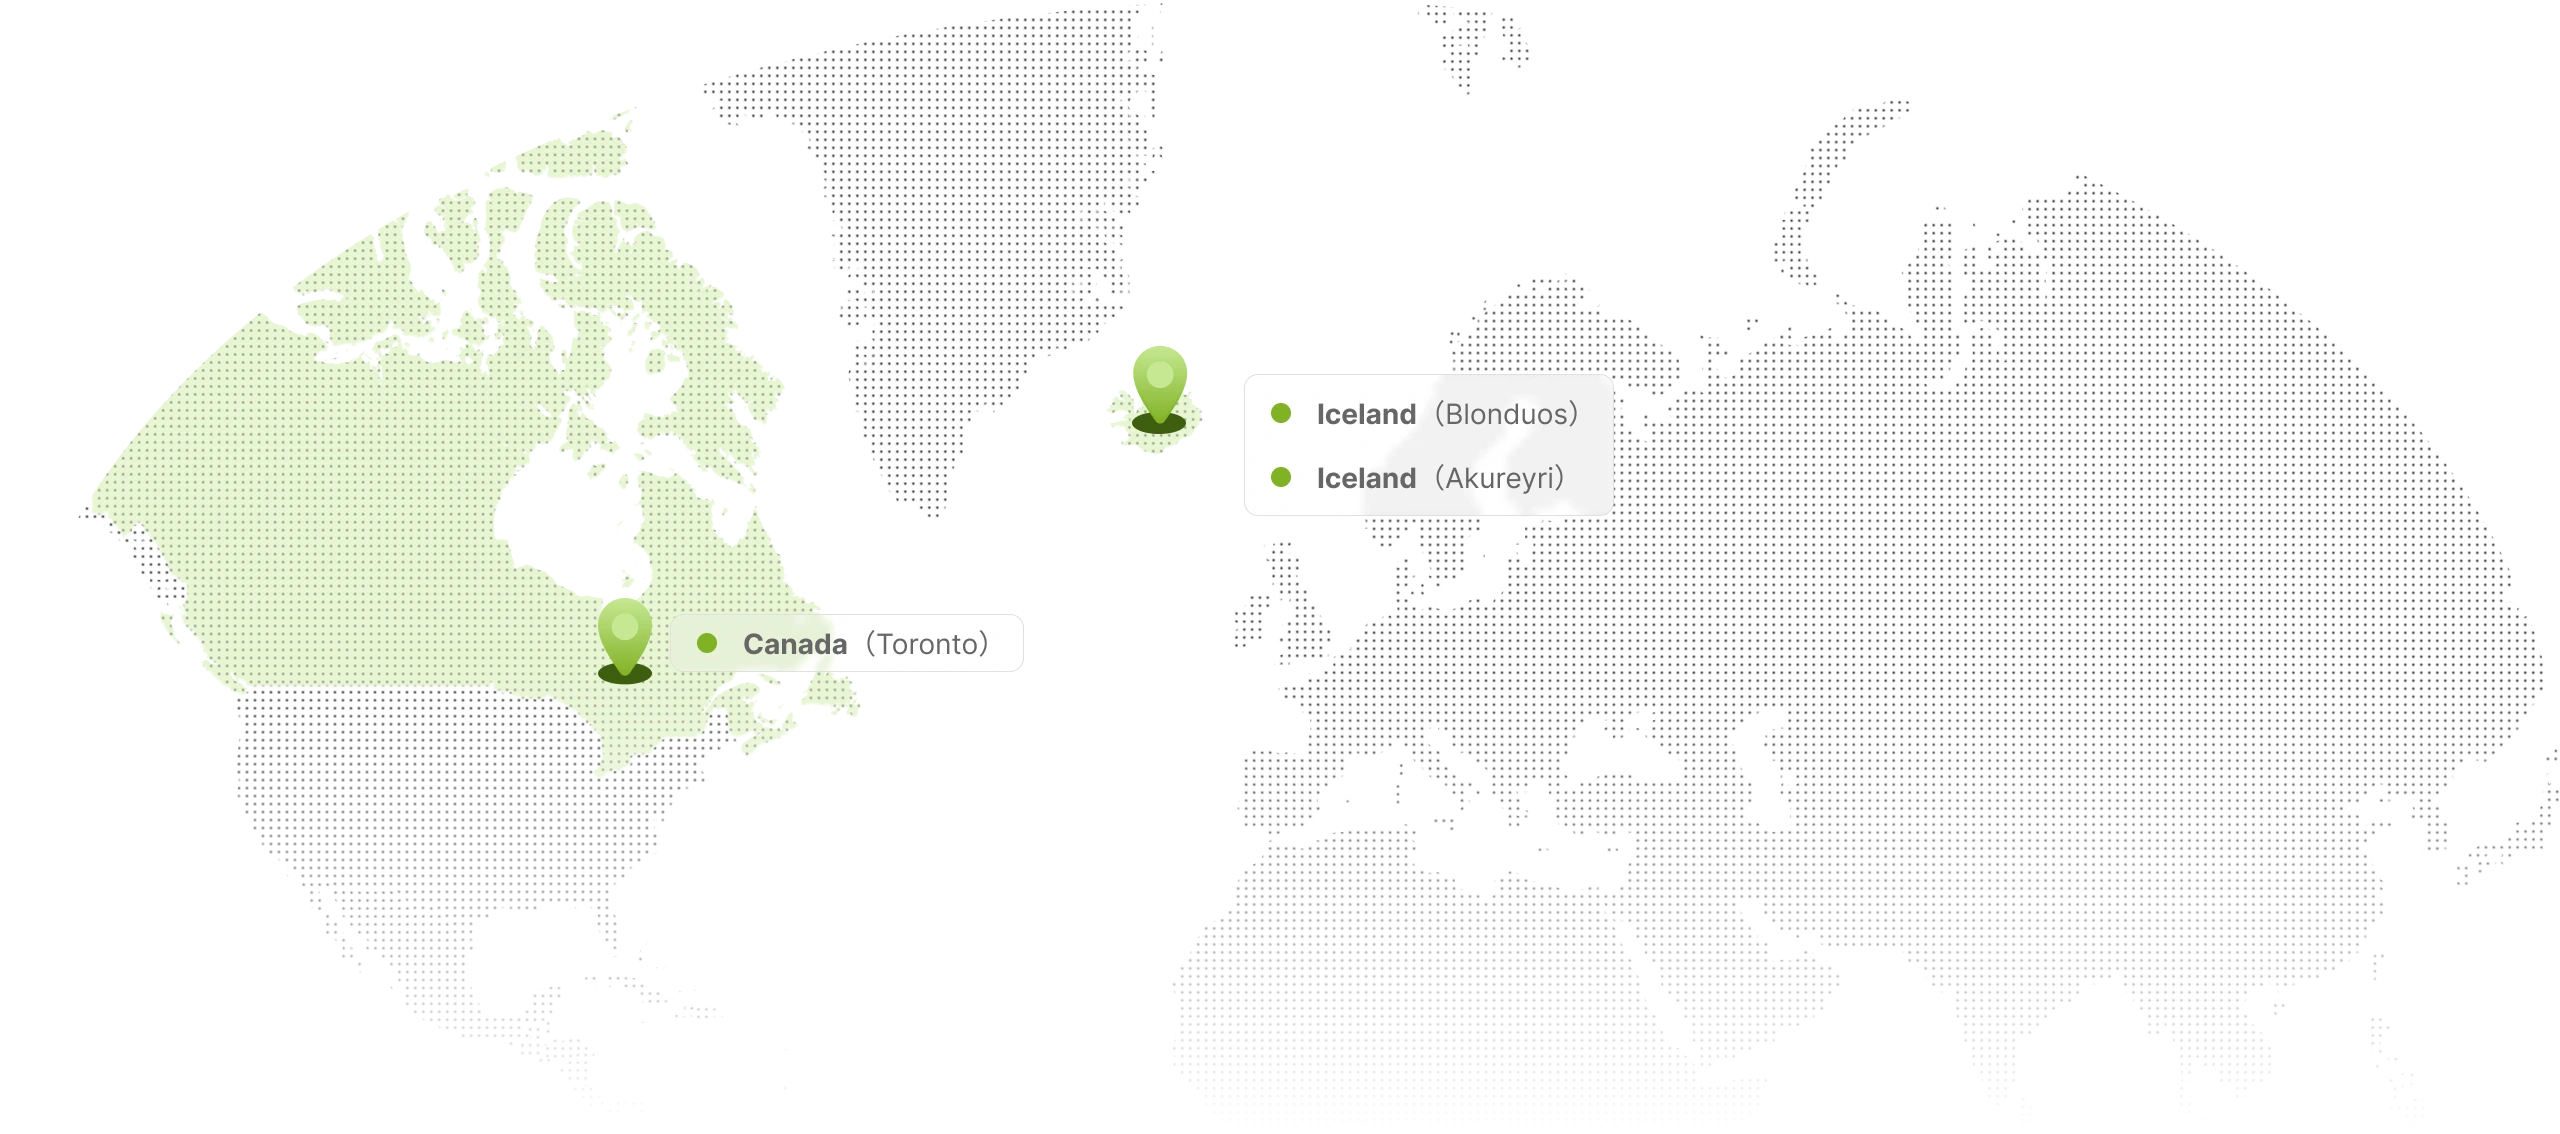
We operate high-performance data centers across key regions worldwide. Explore our coverage map to choose the location that best fits your latency, proximity, and expansion needs.
Questions and Answers

Ready to Build Your NVIDIA-Aligned GPU Cluster?
From architecture design to production-ready delivery, we handle the infrastructure complexity—so your team can focus on building and scaling AI.