

AIDC & GPU Cluster
Management
AIDC & GPU Cluster Management
One Platform to Monitor, Optimize, and Manage AI Infrastructure at Scale.
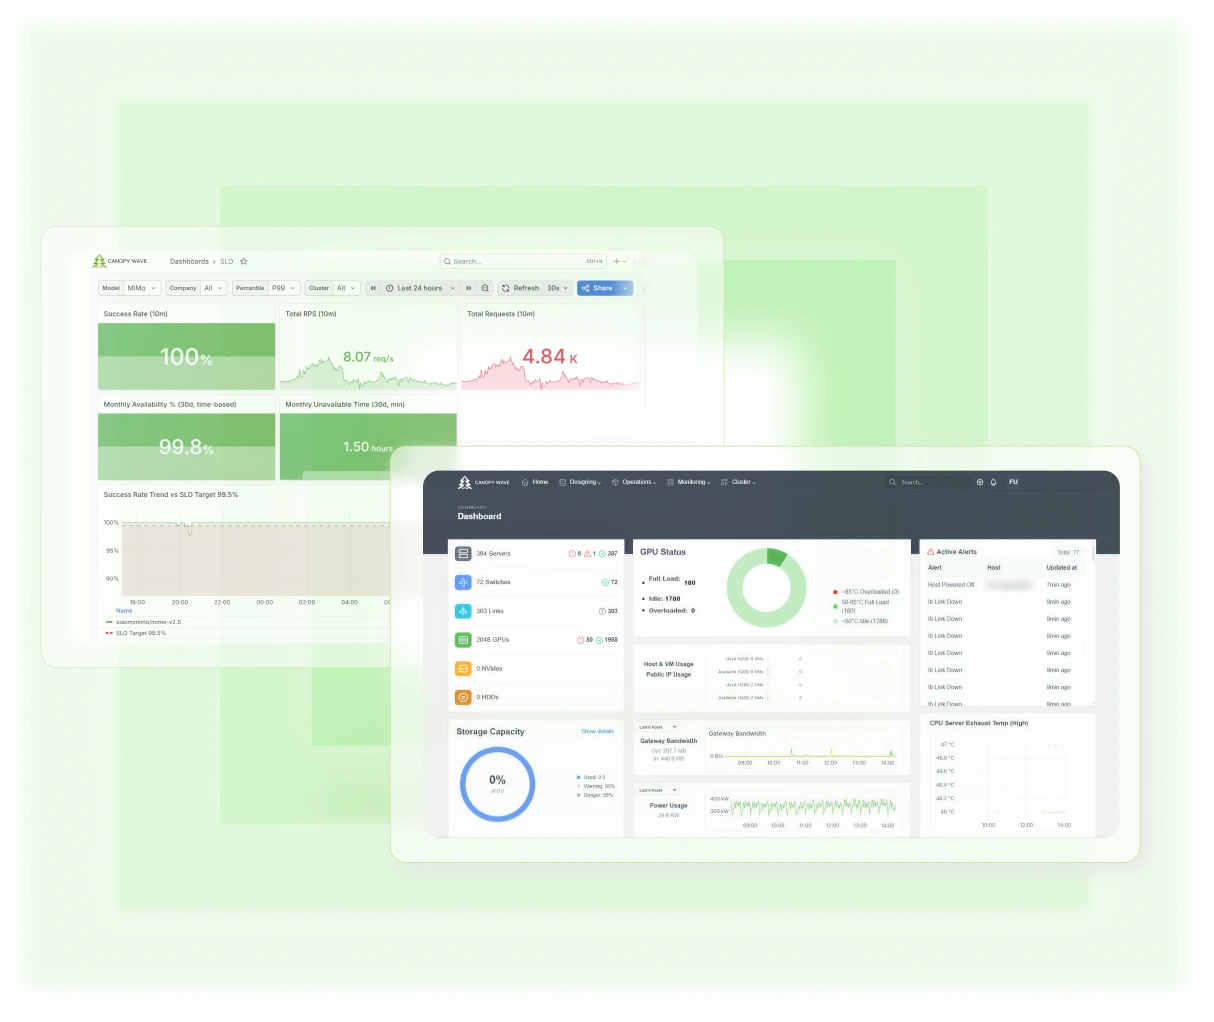
AI Infrastructure Challenges
As GPU clusters grow in scale and power density, traditional infrastructure management approaches are increasingly unable to meet the demands of modern AI data centers.

Complex Performance Optimization
Different hardware/software need extensive manual tuning, slowing deployment and hindering standardized performance.

Fragmented Infrastructure Visibility
Data from GPUs, servers, networking etc. is scattered across tools, blocking a unified infrastructure view.

Complex Asset Management
Assets, configs and changes are managed in silos, making data inaccurate and workflows inefficient.

Slow Fault Detection & Response
Manual detection and response create long gaps from anomaly to resolution, extending incident impact.
One Platform. Complete AIDC Control.
Our self-developed Data Center Infrastructure Management (DCIM) platform, purpose-built for AI infrastructure, brings performance, visibility, operations, and asset management together in one unified platform.
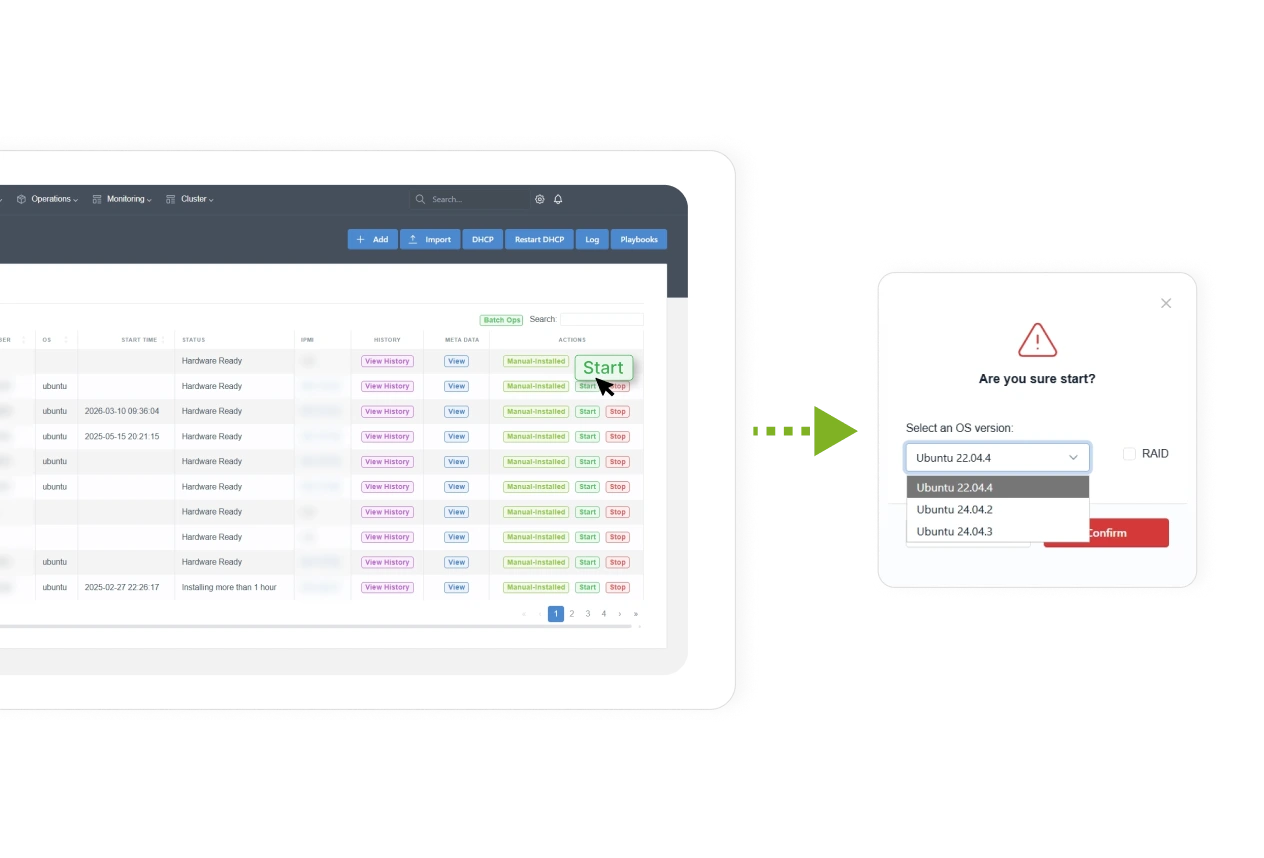
Standardize GPU Performance at Scale
Eliminate repetitive manual tuning. Centrally manage server images, BIOS configurations, driver versions, and other key settings through a unified platform, helping GPU clusters reach optimal performance faster and significantly reducing deployment and tuning time.
Key Capabilities
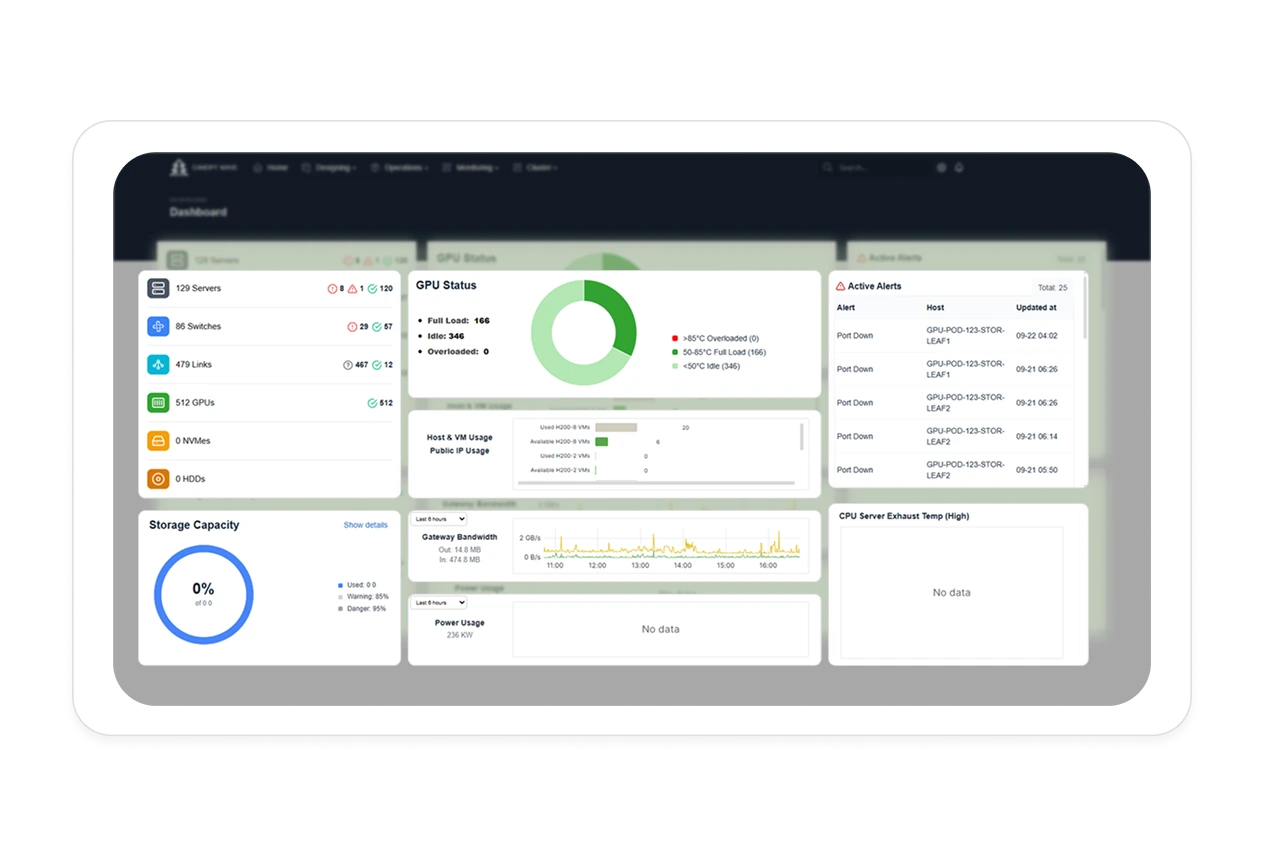
See Your Entire AI Infrastructure at a Glance
Bring GPU, server, networking, storage, power, and thermal data into one unified dashboard for real-time visibility across sites and clusters.
Key Capabilities
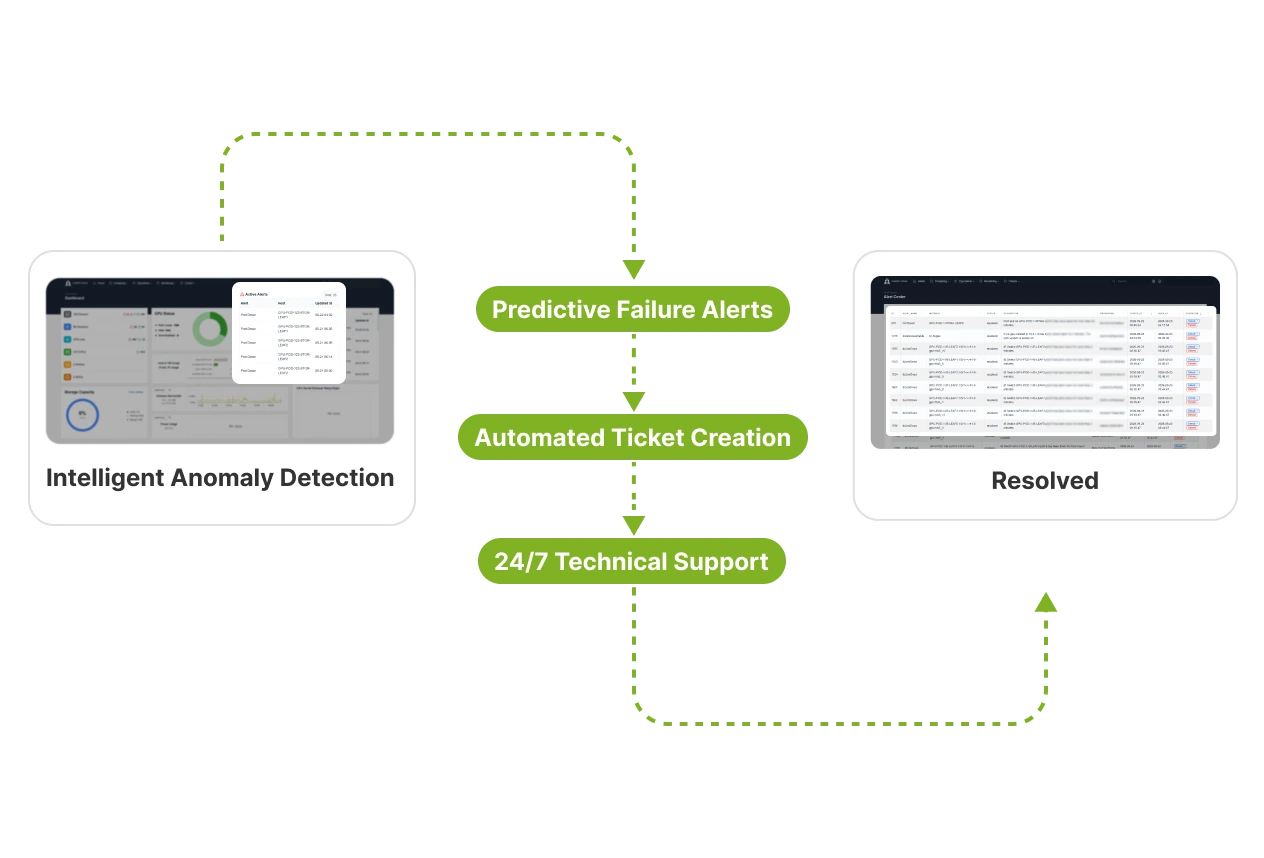
Detect Earlier. Respond Faster.
Continuously analyze infrastructure data to identify anomalies and potential failures, then connect alerts with tickets and operational workflows to turn reactive maintenance into proactive operations.
Key Capabilities
One Source of Truth for Your AI Infrastructure
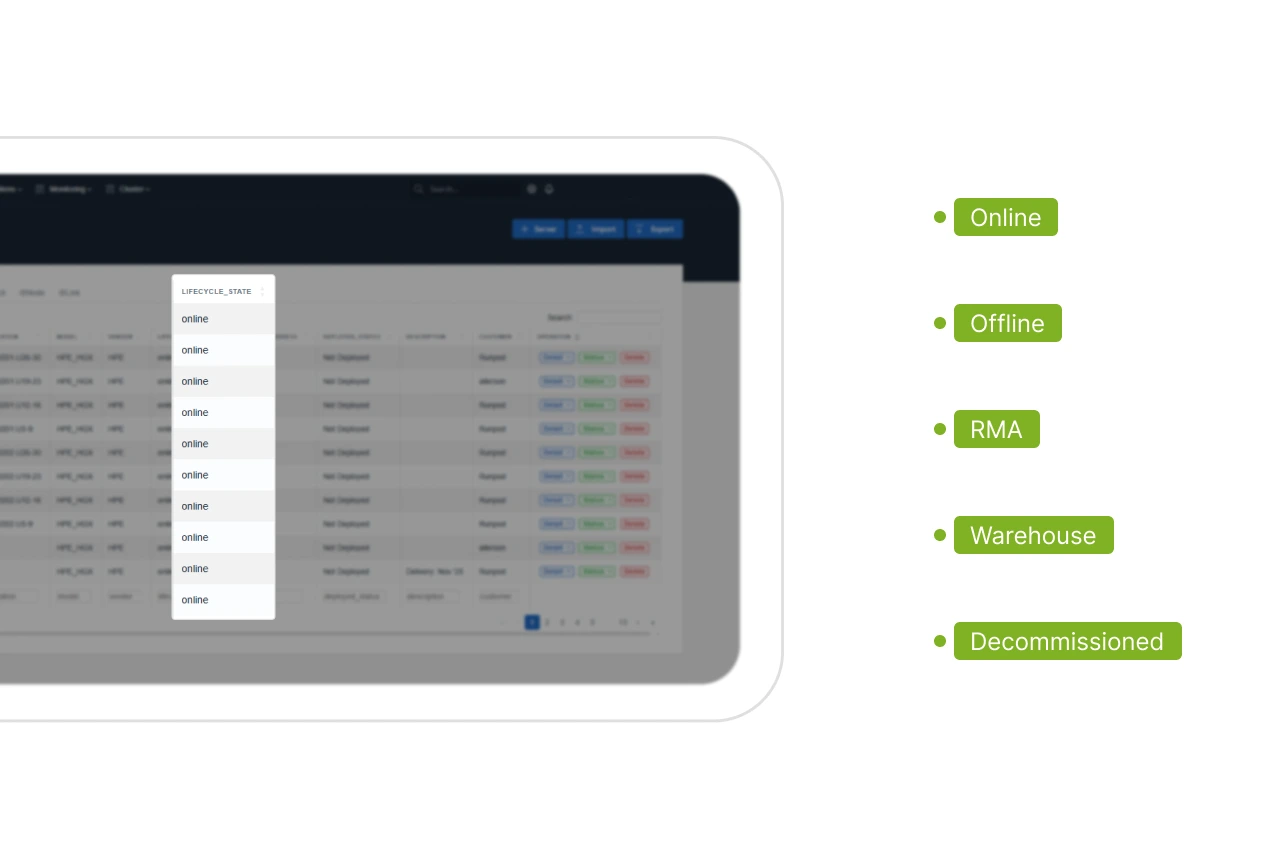
Manage infrastructure assets from deployment and configuration to change, maintenance, and retirement, ensuring accurate asset data, traceable configurations, and auditable changes.
Key Capabilities
Enterprise-Grade Security & Reliability
AI infrastructure requires more than performance. We provide the availability, support, and security standards enterprises need to operate critical workloads with confidence.

99.9% SLA-Backed Availability

Measurable and trackable uptime backed by service-level commitments, helping keep your AI infrastructure running reliably.

24/7 Technical Support

Around-the-clock technical support with minute-level response for critical issues, helping teams identify and resolve incidents quickly.

SOC 2 Type II Certified
Enterprise-grade security and compliance controls designed to protect infrastructure data and support demanding enterprise requirements.
Built for Your GPU Infrastructure Journey
You want to build an AI data center but lack the in-house expertise to design the infrastructure, configure GPU clusters, and manage deployment.
You have invested in GPU infrastructure but don't want to manage complex hardware, monitoring, and maintenance yourself.
Your GPU environment is growing, and you need unified visibility and more efficient operations without adding significant management overhead.
Take Control of Your AI Infrastructure
Built for teams operating high-performance GPU clusters and modern AI data centers. See more. Respond faster. Operate with confidence.