Building production-grade AI infrastructure is one of the biggest challenges facing enterprises today. NVIDIA Reference Architectures (RAs) provide a proven, full-stack blueprint that helps organizations design, deploy, and scale high-performance GPU clusters with confidence.
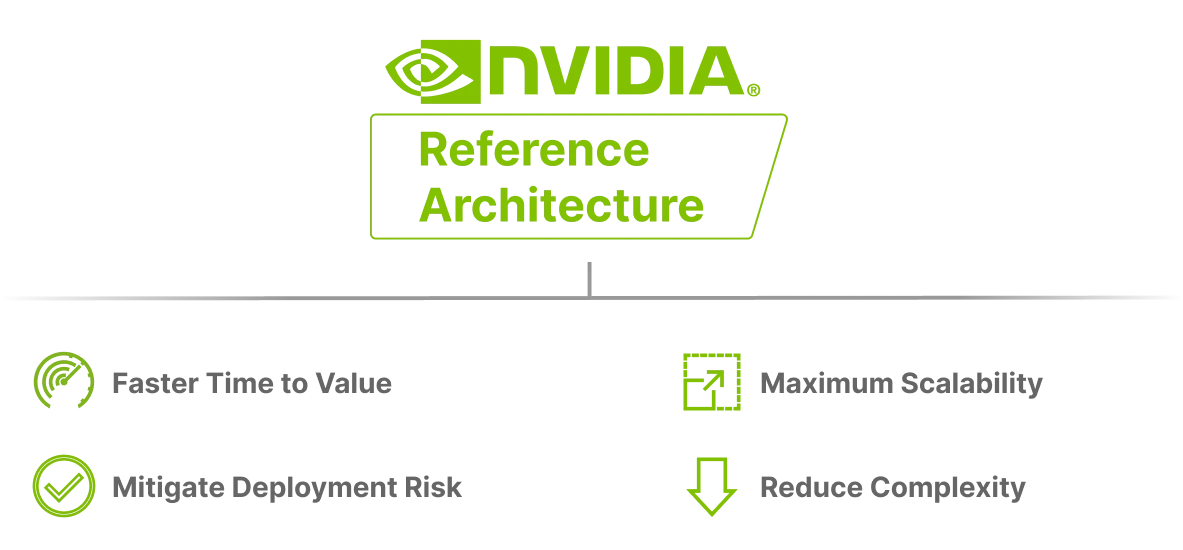
Whether you are planning an on-premises AI Factory, a multi-tenant GPU cloud, or a hybrid AI infrastructure, NVIDIA Reference Architectures significantly reduce complexity, risk, and time-to-value.
What Is an NVIDIA Reference Architecture?
An NVIDIA Reference Architecture is a validated, end-to-end design that covers compute, networking, storage, and software. It integrates NVIDIA-Certified Systems, Spectrum-X Ethernet or InfiniBand networking, BlueField DPUs, and the NVIDIA AI Enterprise software stack into production-ready configurations.
These architectures define optimal node patterns (commonly expressed as C-G-N-B, such as 2-8-5-200), network topologies, scaling models, and operational best practices. The two primary reference architecture families are:
- NVIDIA Enterprise Reference Architecture (ERA) — Designed for enterprise-scale deployments ranging from tens to hundreds of GPUs.
- NVIDIA Cloud Partner Reference Architecture (NCPRA) — Built for large-scale foundation model training and GPU-as-a-Service environments.
Modern implementations further map to practical AI Factory families, including RTX PRO AI Factories, HGX AI Factories, and NVL72 rack-scale systems.
Key Benefits of NVIDIA Reference Architectures
Optimized Performance for AI Workloads
NVIDIA RAs are engineered to maximize the performance of the latest GPUs, NVLink interconnects, and high-speed networking. They deliver high throughput and low latency for generative AI, large language model training and inference, and data analytics.
Flexible Scalability
Organizations can start with small clusters (as few as 4 nodes) and scale to hundreds or thousands of GPUs using proven design patterns. This modular approach reduces upfront investment while supporting long-term growth.
Faster and More Reliable Deployment
Pre-validated hardware and software stacks eliminate much of the integration risk. Resource provisioning, workload management, and monitoring are standardized, accelerating time from design to production.
Enterprise-Grade Security and Reliability
Reference architectures incorporate hardware-level isolation (via BlueField DPUs), rigorous validation, and best practices for multi-tenant environments, helping meet security and compliance requirements.
Improved Cost Efficiency
Standardized designs improve resource utilization and energy efficiency, delivering better performance per watt compared with traditional or ad-hoc infrastructure approaches.
From Blueprint to Production: How Canopy Wave Implements NVIDIA Reference Architectures
Having a validated reference architecture is only the first step. Turning the blueprint into a fully operational, production-ready GPU cluster requires deep expertise and disciplined execution. This is where we specialize.
1. Design
Our engineering team leads full cluster architecture design based on NVIDIA RAs, covering server configuration, high-performance networking (RoCE or InfiniBand), storage architecture, and multi-tenancy requirements from day one.
2. Deploy
We build the cluster and deploy the infrastructure software stack according to NVIDIA standards. Systems ship with GPU drivers pre-installed and networking pre-configured, enabling rapid Day-0/Day-1 bring-up—typically within 1–3 days.
3. Validate
Before delivery, we conduct both small-scale proof-of-concept testing and full-system validation to verify performance, functionality, isolation, and stability under real workloads.
4. Deliver
We hand over the cluster in a ready-to-use state so it can enter production operations immediately. Our Day-2 capabilities support minute-level provisioning, allowing new tenants or workloads to be brought online rapidly through automated OS installation, driver setup, resource isolation, and storage allocation.
Core Capabilities That Enable Successful Implementation
- Specialized Engineering Team — We have deep expertise in NVIDIA GPUs, high-performance networking, system architecture, and AI infrastructure.
- High-Throughput Dual-Tier Storage — We integrate Weka (ultra-low-latency POSIX filesystem with GPUDirect Storage support) for training and checkpointing, combined with Ceph for scalable object and block storage. Storage is cryptographically isolated per tenant.
- Enterprise Security and Reliability
- SOC 2 Type II certified
- Zero-trust isolation enforced at the DPU level
- 99.9% uptime target with full-stack observability
- 24/7 expert technical support
- Global Data Center Footprint — We operate high-performance facilities across key regions, supporting low-latency access and data residency requirements.
By combining NVIDIA’s validated blueprints with rigorous engineering and operational excellence, we transform NVIDIA Reference Architectures into reliable, production-ready AI infrastructure.
Conclusion
NVIDIA Reference Architectures provide the industry’s most trusted blueprint for building scalable, secure, and high-performance AI Factories. When implemented by an experienced team that understands both the architecture standards and real-world operational requirements, they deliver faster deployment, lower risk, and stronger long-term results.